Multiple objectives, MMoE, and pre-ranking
Goal
Turn concepts into inspectable inputs, operations, gradients, and comparisons.
Evidence: controlled simulation, not impression CTR. Local teaching parameters are not production defaults; mechanism experiments are not full reproductions of the original papers.
English companion. All instructional Markdown is translated. Experiment code, Chinese language examples, execution counts, and saved outputs remain as in the source edition; historical output text may therefore be Chinese. The initial setup cell anchors the working directory and Python import path for this companion's deeper folder; it does not change the experiment. Saved outputs are historical evidence, not a new run. Run from the top after preparing the required data and models.
# English companions live one directory deeper; keep the original experiment code unchanged.
from pathlib import Path as _TranslationPath
import os as _translation_os
import sys as _translation_sys
_translation_root = next((p for p in [_TranslationPath.cwd(), *_TranslationPath.cwd().parents]
                          if (p / "reclab").is_dir()), None)
if _translation_root is None:
    raise RuntimeError("Open this notebook from inside the Search Recommendation Ads Lab checkout.")
_translation_os.chdir(_translation_root)
if str(_translation_root) not in _translation_sys.path:
    _translation_sys.path.insert(0, str(_translation_root))
Setup
On the first pass, run from Setup in order: later cells reuse earlier variables. Then change one parameter and rerun that cell and its downstream cells. Constructed data does not establish real business impact.
from pathlib import Path
import sys
import inspect
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
from IPython.display import display, Code

PROJECT = next(p for p in [Path.cwd(), *Path.cwd().parents]
               if (p / "reclab/models.py").exists())
if str(PROJECT) not in sys.path:
    sys.path.insert(0, str(PROJECT))
from reclab.data import Dataset
from reclab.paths import ARTIFACTS, PROCESSED, read_json

plt.rcParams.update({"figure.figsize": (9, 3.8), "font.size": 11,
    "axes.spines.top": False, "axes.spines.right": False,
    "axes.labelcolor": "#182b2b", "text.color": "#182b2b",
    "axes.facecolor": "white", "figure.facecolor": "white",
    "grid.color": "#d4ddda", "axes.axisbelow": True})
dataset = Dataset()
print("Project:", PROJECT)
print("Dataset version:", dataset.manifest["dataset_version"])
print("Python:", sys.executable)
assert Path(sys.executable).parent == PROJECT / ".venv/bin", "请选择 Recommendation Lab 内核"
Saved notebook output · not executed on this page
Project: /Users/lizuolin/local/recommendation-lab
Dataset version: 2772cab0aca8cb81
Python: /Users/lizuolin/local/recommendation-lab/.venv/bin/python
Steps
Lecture references: 03_Rank_01.pdf, 03_Rank_02.pdf, 03_Rank_03.pdf, 03_Rank_04.pdf, 03_Rank_05.pdf, 03_Rank_06.pdf
Conditional probabilities, score fusion, and sampling correction
All probabilities here are constructed. Correction depends on a known sampling mechanism and cannot be applied directly to logs without an impression denominator.
Predict first: What is expressed by multiplying conditional probabilities, versus adding arbitrary prediction scores?
from reclab.learning.networks import (calibrate_negative_sampling,
    fit_multitask, MMoE, ThreeTower)
import torch
from torch.nn import functional as F
torch.manual_seed(42); torch.set_num_threads(4)
pc=np.array([.2,.4,.15]); cart=np.array([.3,.1,.5]); pay=np.array([.4,.6,.3]); price=np.array([20.,100.,50.])
display(pd.DataFrame({"p_pay":pc*cart*pay,"expected_revenue":pc*cart*pay*price,"weighted_sum_proxy":pc+cart+pay}))
true=np.array([.01,.1,.5]); alpha=.1
sampled=true/(true+alpha*(1-true))
recovered=calibrate_negative_sampling(sampled,alpha)
assert np.allclose(true,recovered)
display(pd.DataFrame({"true":true,"sampled":sampled,"recovered":recovered}))
Saved notebook output · not executed on this page
| p_pay | expected_revenue | weighted_sum_proxy | |
|---|---|---|---|
| 0 | 0.0240 | 0.480 | 0.90 |
| 1 | 0.0240 | 2.400 | 1.10 |
| 2 | 0.0225 | 1.125 | 0.95 |
| true | sampled | recovered | |
|---|---|---|---|
| 0 | 0.01 | 0.091743 | 0.01 |
| 1 | 0.10 | 0.526316 | 0.10 |
| 2 | 0.50 | 0.909091 | 0.50 |
Tasks and gates in MMoE
Controlled synthetic labels; fitting them does not demonstrate real recommendation gains. Task correlation is directly adjustable.
Predict first: If task correlation becomes 0, must the gates separate and performance improve?
TASK_CORRELATION=.7
x=torch.randn(512,6); signal=x[:,0]+x[:,1]*x[:,2]
other=TASK_CORRELATION*signal+(1-TASK_CORRELATION)*(x[:,3]-x[:,4])
y=torch.stack([(signal>0).float(),(other>0).float()],-1)
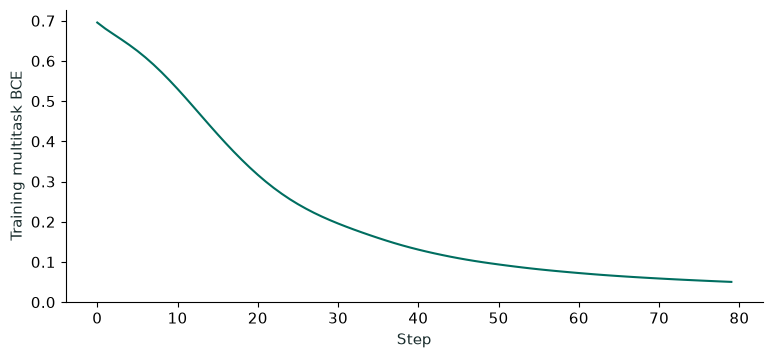
model,curve=fit_multitask(x,y,steps=80)
logits,gates=model(x)
display(Code(inspect.getsource(MMoE),language="python"))
display(pd.DataFrame(gates.mean(0).detach().numpy(),index=["task1","task2"],columns=["expert1","expert2","expert3"]))
assert torch.allclose(gates.sum(-1),torch.ones_like(gates.sum(-1)),atol=1e-6)
assert curve[-1]<curve[0]
plt.plot(curve,color="#006e60");plt.xlabel("Step");plt.ylabel("Training multitask BCE");plt.ylim(bottom=0);plt.show()
Saved notebook output · not executed on this page
class MMoE(nn.Module):
    def __init__(self, input_dim, experts=3, tasks=2, hidden=12):
        super().__init__()
        self.experts = nn.ModuleList(
            [
                nn.Sequential(nn.Linear(input_dim, hidden), nn.ReLU())
                for _ in range(experts)
            ]
        )
        self.gates = nn.ModuleList(
            [nn.Linear(input_dim, experts) for _ in range(tasks)]
        )
        self.heads = nn.ModuleList([nn.Linear(hidden, 1) for _ in range(tasks)])

    def forward(self, x):
        experts = torch.stack([expert(x) for expert in self.experts], 1)
        weights = [gate(x).softmax(-1) for gate in self.gates]
        logits = torch.cat(
            [
                head((experts * w.unsqueeze(-1)).sum(1))
                for w, head in zip(weights, self.heads)
            ],
            -1,
        )
return logits, torch.stack(weights, 1)| expert1 | expert2 | expert3 | |
|---|---|---|---|
| task1 | 0.426174 | 0.263568 | 0.310258 |
| task2 | 0.389943 | 0.395034 | 0.215022 |
<Figure size 900x380 with 1 Axes>
Watch-time-weighted logistic regression
There are no real duration labels. Constructed durations check the constant model's mathematical optimum. Optimal odds equal the sum of positive weights divided by the number of negatives, not ordinary CTR.
Predict first: What happens to optimal odds if all positive durations double?
durations=torch.tensor([10.,20.,30.]); negative_count=12
z=torch.nn.Parameter(torch.tensor(0.)); opt=torch.optim.Adam([z],lr=.1)
for _ in range(220):
    opt.zero_grad()
    loss=-(durations.sum()*F.logsigmoid(z)+negative_count*F.logsigmoid(-z))/15
    loss.backward();opt.step()
expected=float(durations.sum())/negative_count
print("Learned odds:",float(torch.exp(z.detach())),"closed form:",expected)
assert abs(float(torch.exp(z.detach()))-expected)<.05
Saved notebook output · not executed on this page
Learned odds: 5.000090599060059 closed form: 5.0
User, item, and cross-feature towers
A small model of the lecture's pre-ranking mechanism, not complete COLD. Random features check only cache equivalence.
Predict first: Which features can be cached, and which vary by candidate or request?
ranker=ThreeTower(dim=8)
u=torch.randn(1,8); items=torch.randn(40,8); cross=torch.randn(40,8)
cached=ranker.cached_score(u,items,cross)
looped=torch.stack([ranker.cached_score(u,items[i:i+1],cross[i:i+1])[0] for i in range(40)])
assert torch.allclose(cached,looped,atol=1e-6)
display(Code(inspect.getsource(ThreeTower),language="python"))
print("User encoding: cached=1, naive=40. Cross features still run per candidate.")
Saved notebook output · not executed on this page
class ThreeTower(nn.Module):
    """Cached user/item representations plus per-candidate interaction; not full COLD."""

    def __init__(self, dim=8, hidden=12):
        super().__init__()
        self.user = nn.Linear(dim, hidden)
        self.item = nn.Linear(dim, hidden)
        self.cross = nn.Linear(dim, hidden)
        self.head = nn.Linear(hidden * 3, 1)

    def cached_score(self, user_vector, item_vectors, cross_features):
        u = self.user(user_vector).expand(len(item_vectors), -1)
        return self.head(
            torch.cat([u, self.item(item_vectors), self.cross(cross_features)], -1)
        ).squeeze(-1)
User encoding: cached=1, naive=40. Cross features still run per candidate.
Checks
Every assertion and output is traceable to code. They check operators, data snapshots, or mechanisms, not online gains.
Next steps
Record your prediction, change only one variable, and run the relevant experiment cell. Open reclab/learning/ to inspect helper functions.